Parsewise Data Engine is the core technology inside Parsewise. It reads entire document corpora, builds a structured world model of what it finds, and learns from every correction.
The way business users work with unstructured documents has not changed for decades.
A structured world model
PDE is built around a structured world model: a persistent, structured representation of everything known about the task and information available.
The result is document intelligence that does not go off the rails when scale or complexity increases.
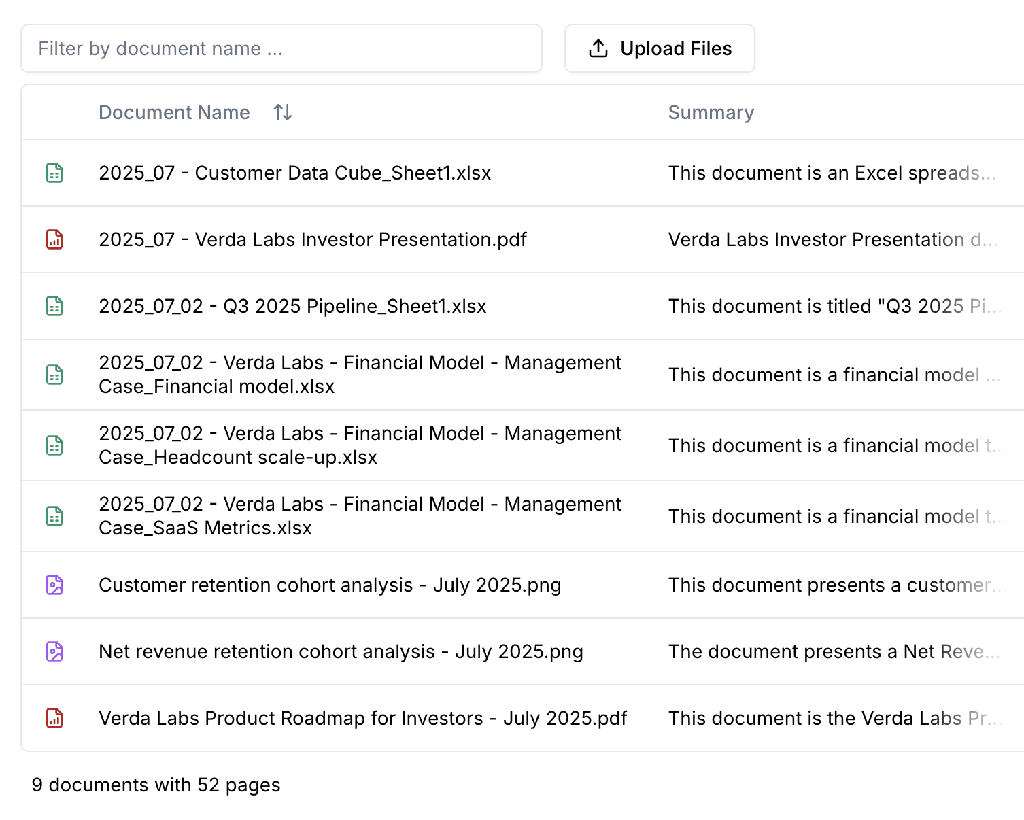
Every file in the corpus, in any format.
A persistent representation of everything known about the task.
Which supplier contracts reprice after year 3?
4 contracts reprice after year 3. Two cap increases at CPI.
Exhaustive
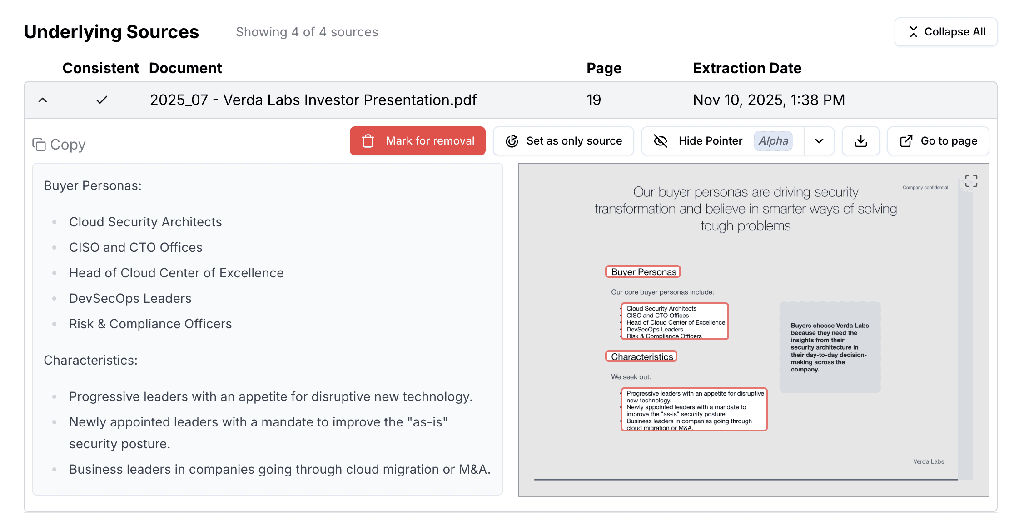
Every page in the corpus is read and cross-checked against every other page, not just the ten closest snippets.
Self-learning
Corrections and reviews train the engine directly, not a prompt. Accuracy compounds with use.
Accountable
Every answer cites the exact pages it came from, so every number can be defended.
Retrieval reads a sample. PDE reads the corpus.
A single run spans more than 25,000 pages and continues autonomously for over five hours.
It skims a few fragments, then guesses at the rest.
PDE reads and cross-checks every page. Edge cases surface instead of hiding.
Five systems, one engine
Cross-Document Attention
Modeling relationships across an entire document corpus simultaneously.
- Capture links, contradictions, and dependencies across entire corpora
- Eliminate hallucinations by grounding outputs in all relevant sources
- Never miss edge cases hidden outside retrieved snippets
RL from User Interactions
Continuous learning system that adapts to real context.
- Trains policies directly from real user behavior, not synthetic proxies
- Captures domain-specific preferences that static models miss
- Continuously improves relevance, judgment, and workflow fit
Enterprise Scalability
Production-grade infrastructure for very large document packages.
- Processes hundreds of thousands of pages per run with predictable SLAs
- Elastic orchestration, queuing, and retries for spiky workloads
- Central monitoring, audit, and versioning across projects
KPI-Specific Models
Precision models tuned and validated for business KPIs.
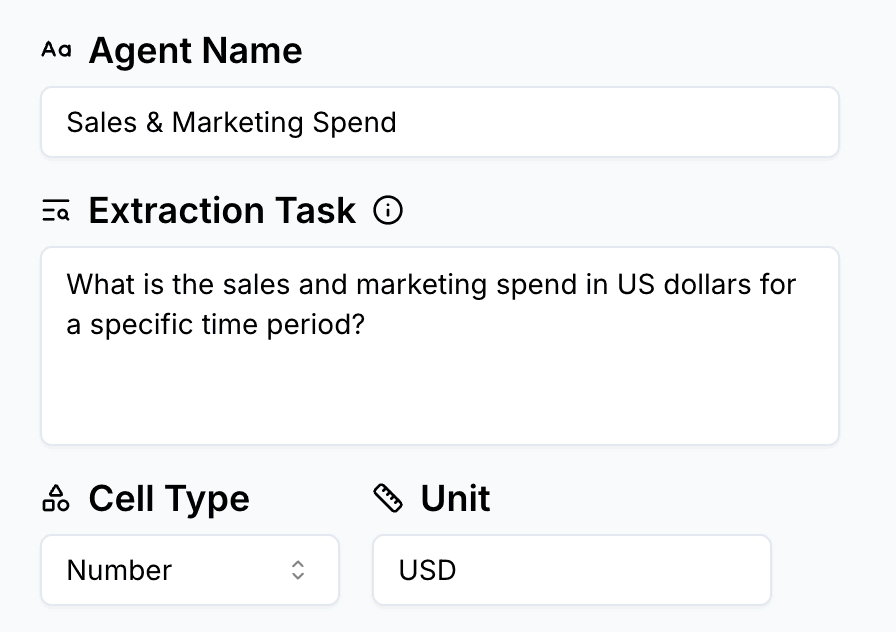
- Built for narrow, high-value tasks using targeted fine-tuning
- Outperform general models on structure, accuracy, and edge-case handling
- Capture domain logic from real documents and user habits
Automated Ontology Generation
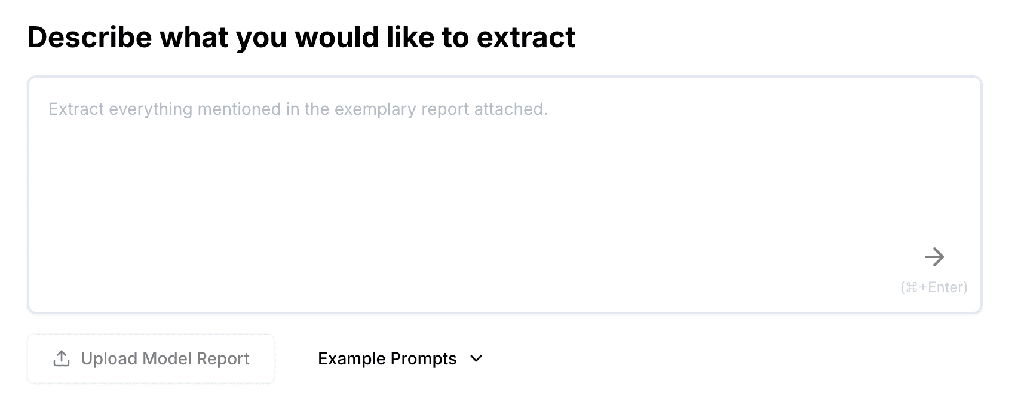
Business-ready structure without engineers.
- Generates and updates domain ontologies through natural interaction
- Removes technical barriers, enabling teams to adapt structure
- Integrates cleanly with existing databases and enterprise systems
Join us!
If you have world-class experience in any of the above areas or adjacent fields, please reach out. We are always hiring exception engineers!